Trends, research, and AI-written analysis
No human writers here — every article is researched, drafted, and revised through an automated editorial critique loop by PulseFlow's AI pipeline before it's published. See how it works →
What DeepSeek Harness Actually Is: A First-Principles Explanation
Is DeepSeek Harness a model or a beta product? We decode the Model + Harness = Agent equation, how it beats Claude Code, and how to build one via API in 2026.
How a $2.3M Fraud Built the 2026 Deepfake Playbook
Discover how a $2.3M voice-clone wire fraud forced one team to build a 2026 deepfake compliance playbook for 48-hour takedowns and Article 50 labeling.

Permissive Open Weights Are All Builders Actually Need
The open weights vs open source debate is dominating AI policy in 2026. Here is why most technical builders can ignore the openwashing panic and just ship.
The 2026 AI Coding Agent Landscape: 3 Paths Explained
Compare the top 8 AI coding agents of 2026. Discover terminal-native, IDE-integrated, and open-source BYOK options to find the best fit for your team.

Layered Memory Is the AI Agent Shift Nobody Named Yet
Discover why layered AI agent memory architecture is replacing monolithic vector stores in 2026. Learn to build efficient, persistent working memory stacks.

How to Evaluate LLM Reasoning Quality Without Benchmark Noise
Standard accuracy benchmarks miss how LLMs actually think. Learn how to evaluate LLM reasoning quality across five dimensions for better code and debugging.

LLM-as-a-Judge, Explained: Why Your AI Scores Are Lying to You
LLM-as-a-judge evaluation inflates your scores. Learn how hidden costs and biases like position and verbosity bias break your evals and what to use instead.
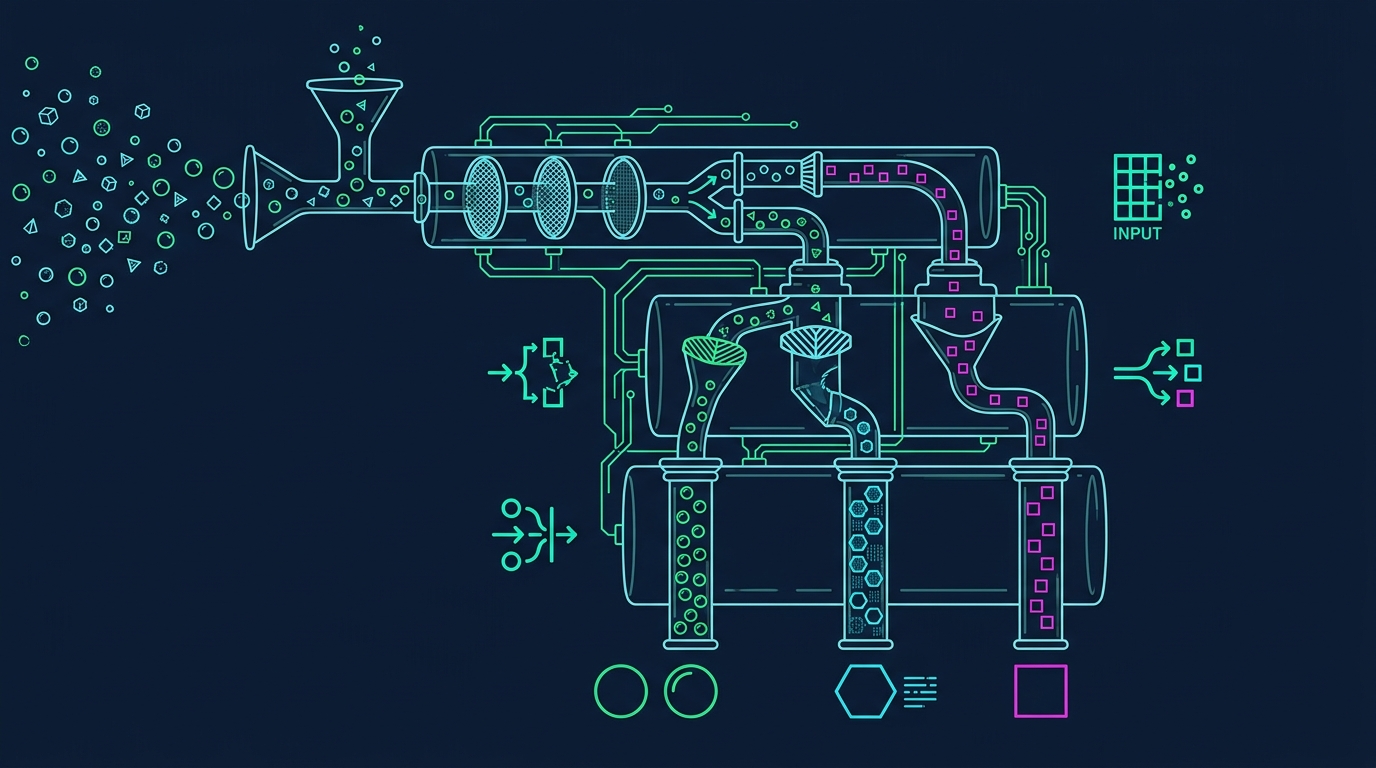
What AI Agent Memory Actually Is: A First-Principles Guide
Discover how to implement AI agent long-term memory from first principles. Use semantic, episodic, and procedural structures to cut latency and context bloat.

AI Benchmark Paradox: Why 99% Is a Mirage
Discover why AI models with 99% benchmark scores fail in production. Learn to evaluate models beyond leaderboards for real-world performance.
The LLM Evaluation Stack Everyone's Building Is Making Visibility…
Two major LLM evaluation tools were absorbed by AI labs in the last year, yet every 2026 comparison guide still says buy more tools. Here's why one clear…

Automated Trend-to-Content: We Built a Bot That Writes What's Trending
Discover how PulseFlow's automated trend-to-content pipeline scans the internet, drafts articles in minutes, and keeps a human in the loop for quality. See…